


New
Reasoning traces are live

See how your
model thinks.
Lumen shows the steps behind every AI answer, so your team can debug faster, prove quality, and ship with confidence.

Drops into the stack you already run
Why we built
Lumen
AI should make things clearer, not louder. Lumen is the observability layer for teams shipping AI into real products. Every answer comes with the steps behind it: what the model planned, what it retrieved, which tools it called and why. When something breaks, you see where, fix it once and prove it stays fixed.
Trusted by teams shipping AI in production


Features
Fewer black boxes.
More answers you can trust.


How it works
From first trace to trusted in an afternoon.
Step 1
Connect
Wrap your existing model client. Two lines, any provider, no changes to your prompts.
import lumen
client = lumen.wrap(client)
Step 2
Watch
Every request becomes a trace you can open, replay and share with your team.
lumen.trace(“refund-check”)
→ 14 steps · 1.24s
Step 3
Improve
Turn good and bad traces into evals, then gate each deploy on the result.
lumen eval run golden-set
✓ 96.3% passed
Platform
Better insights.
Fewer tools.
Works with the stack you already run
Lumen plugs into any model provider, open-weight model, vector store or agent framework. Traces, evals and guardrails share one timeline, so nobody stitches dashboards together again.
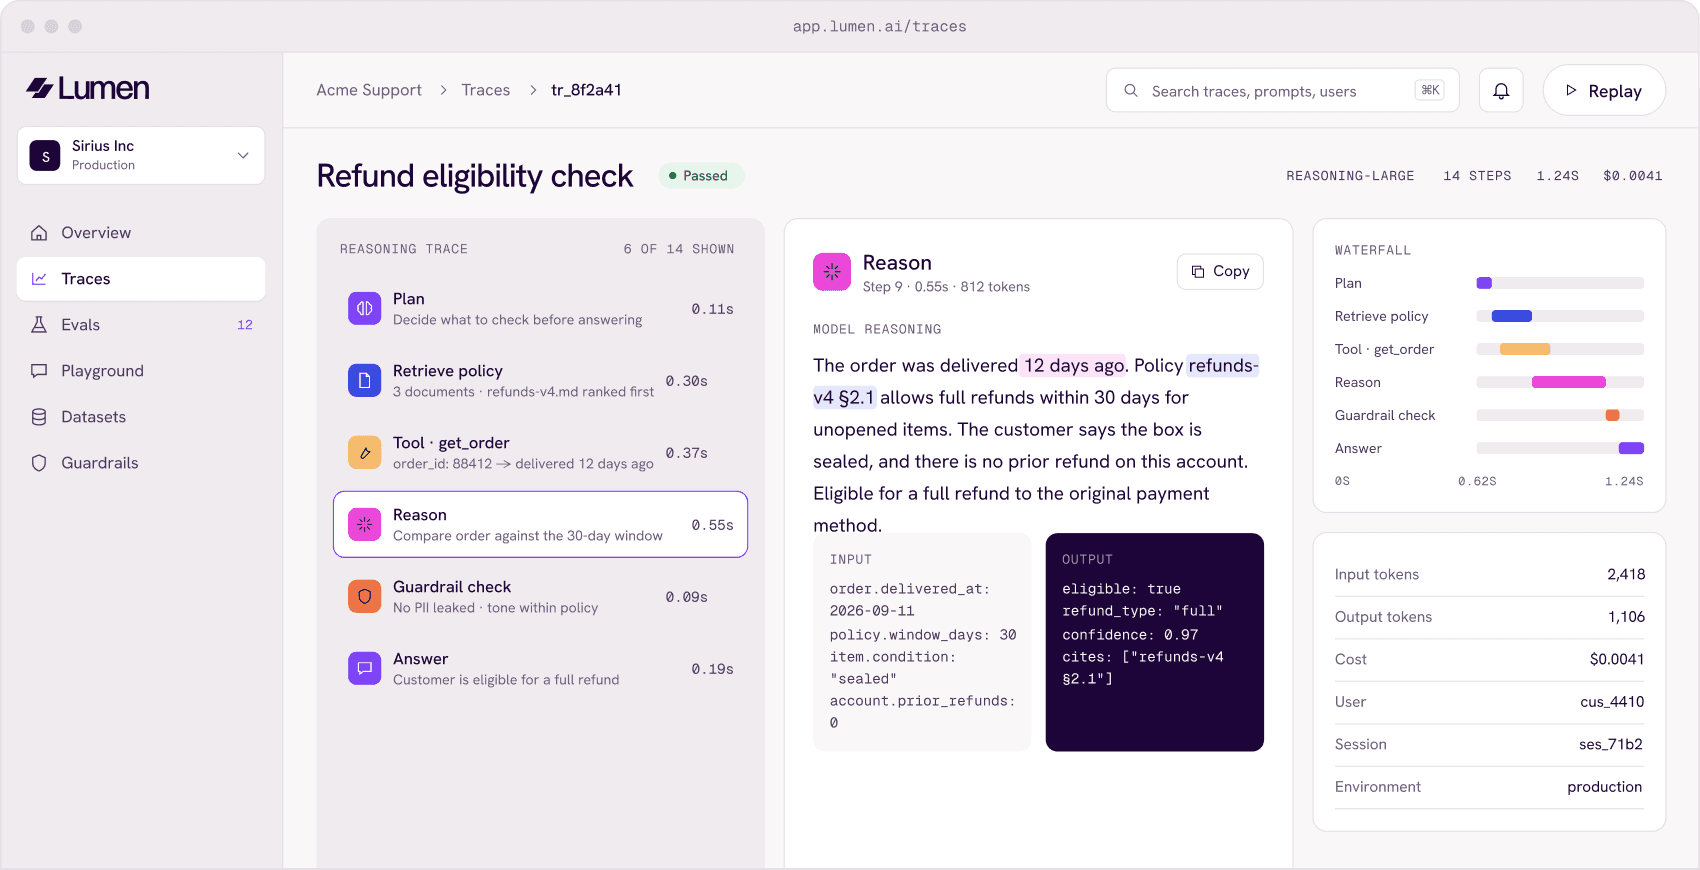

Traces
Every request,
every step.


Trace detail
Answers you can
trace to the source.
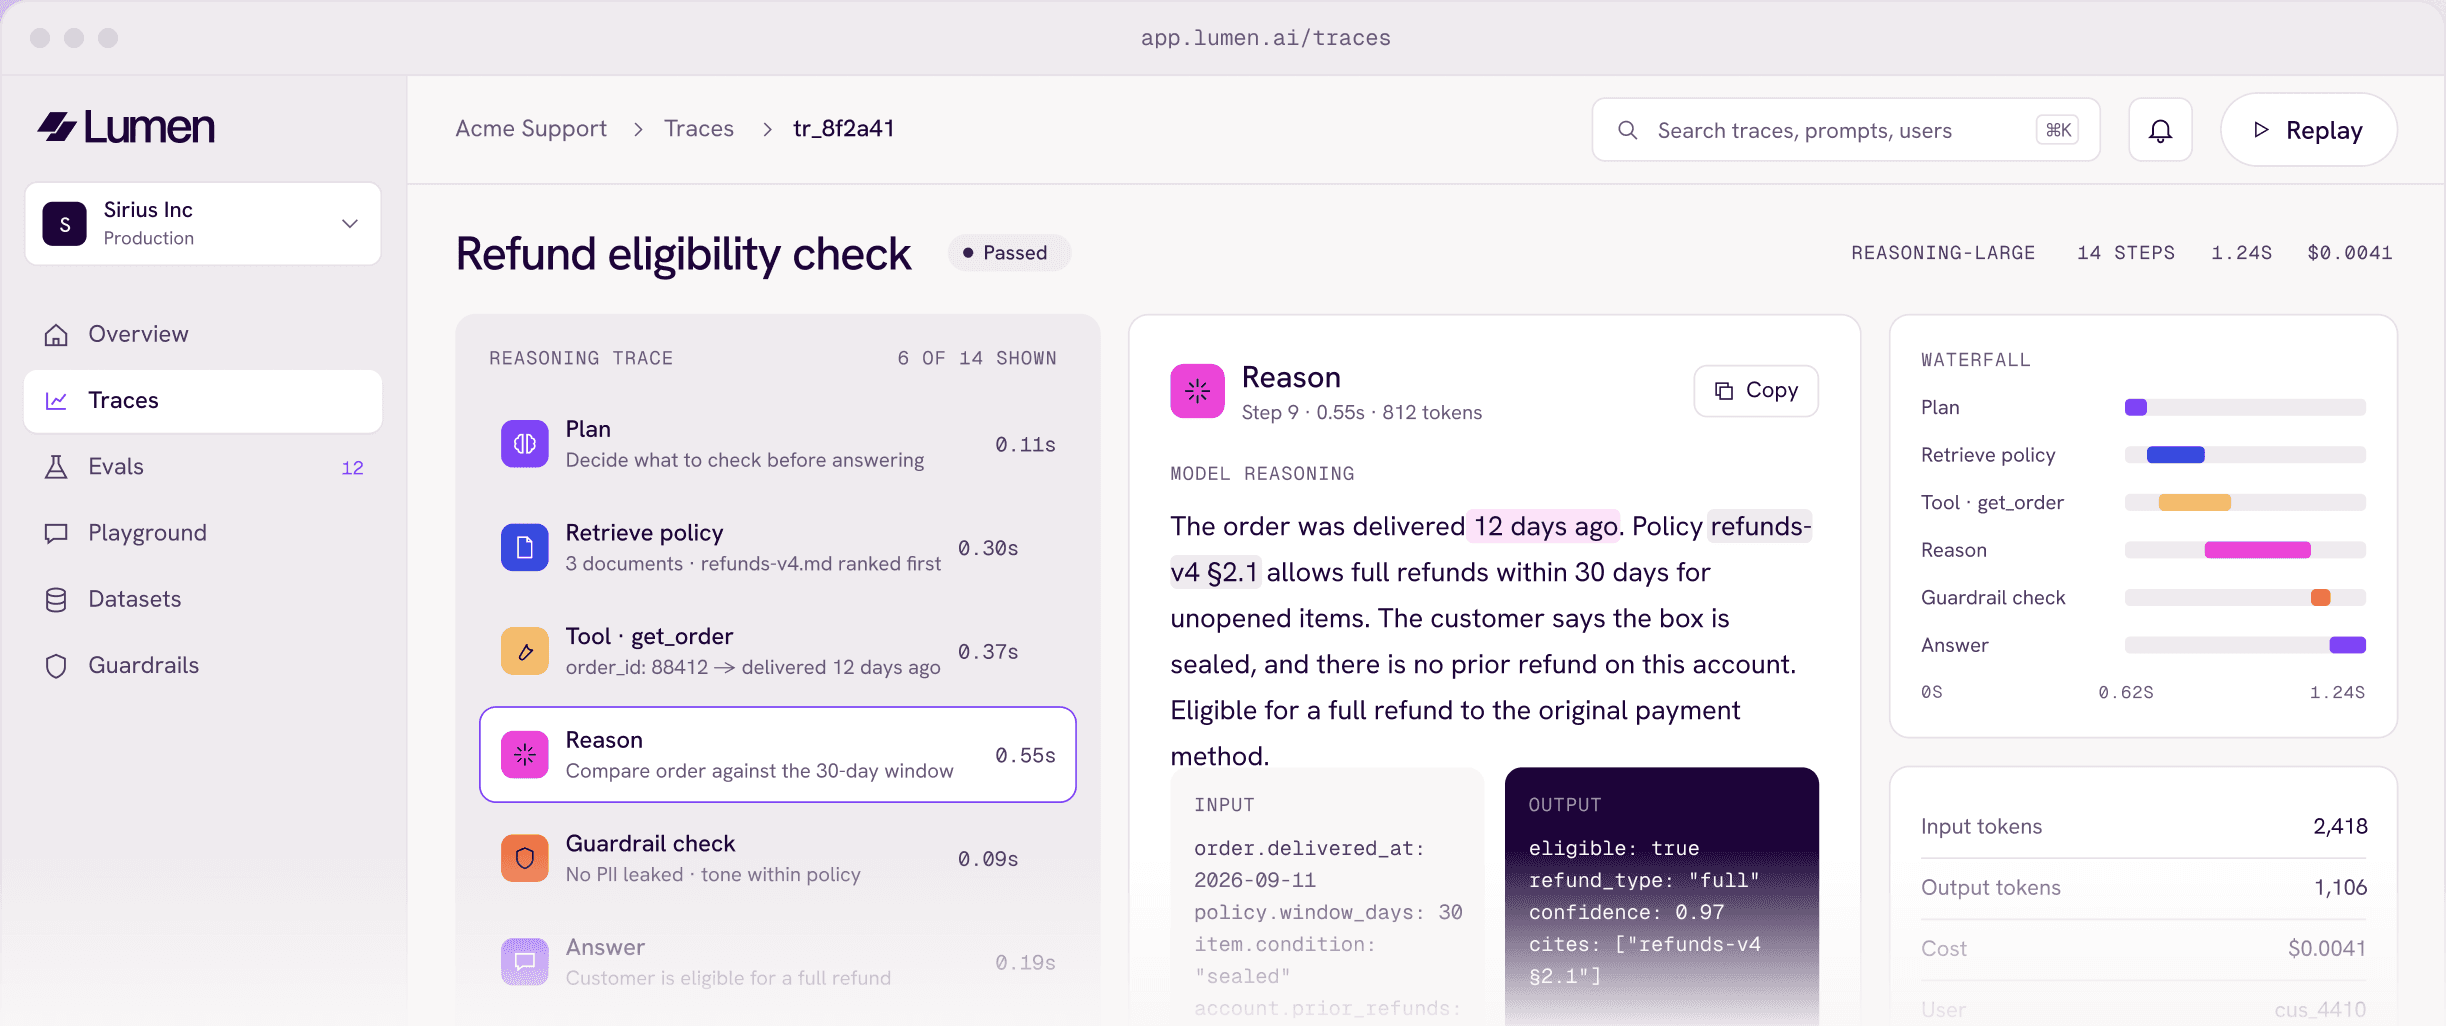

Playground
Replay it. Fix it.
Ship it.


Testimonials
Teams that
stopped guessing.
Pricing
Start free.
Scale when it matters.
$0
free forever
Starter · for side projects and first traces
100k traced tokens a month
7-day trace retention
1 project
Evals on up to 50 cases
Community support
$49
per seat / month
Team · for AI running in production
10M traced tokens a month
90-day trace retention
Unlimited projects
Evals and deploy gates
Guardrails and PII redaction
Replay in the playground
SSO and role-based access
Slack and email alerts
Email support, 1-day response
FAQ
Questions,
answered.
Short answers to what teams ask before they start tracing. Can’t find yours? An engineer will reply within one working day.
Common questions
Which models and providers does Lumen support?

How long does setup take?
Where is our trace data stored?
Can Lumen redact personal data?
How is pricing calculated?
Can we self-host Lumen?

Wrap your model client, send a request and open the trace. Free up to 100k traced tokens a month, no card needed.